Applied AI / RAG / 2026
AI-Powered Legal Research Assistant
Retrieval-grounded research workflows that connect natural-language questions with supporting NSW legal material.
SOFT3888 capstone · Vecton AI client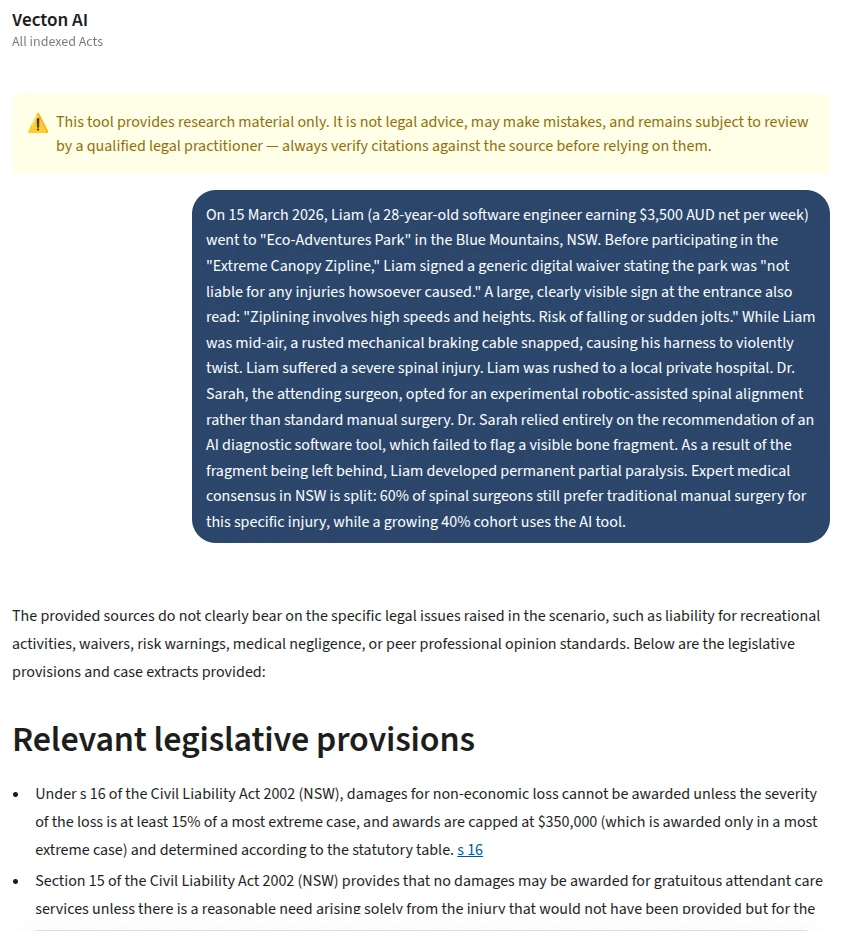
The problem
01Legal research requires finding relevant material and tracing a claim back to its source. Fluent generated text alone cannot establish that a legal proposition is supported. The project focuses on retrieval and source traceability within a defined corpus.
Team & contribution
Built with my team for the University of Sydney’s SOFT3888 capstone unit, with Vecton AI as our client. The engineering work described here is a shared team effort. The legal research assistant material is owned by Vecton AI.
Approach & architecture
02Ask
Natural-language research in Streamlit
Retrieve
BGE embeddings and ChromaDB vector search
Orchestrate
LangChain / LangGraph workflows with Ollama
Trace
Source documents and SQLite-backed data
Conceptual system flow, based on the project summary.
Engineering decisions
03Keep the corpus bounded
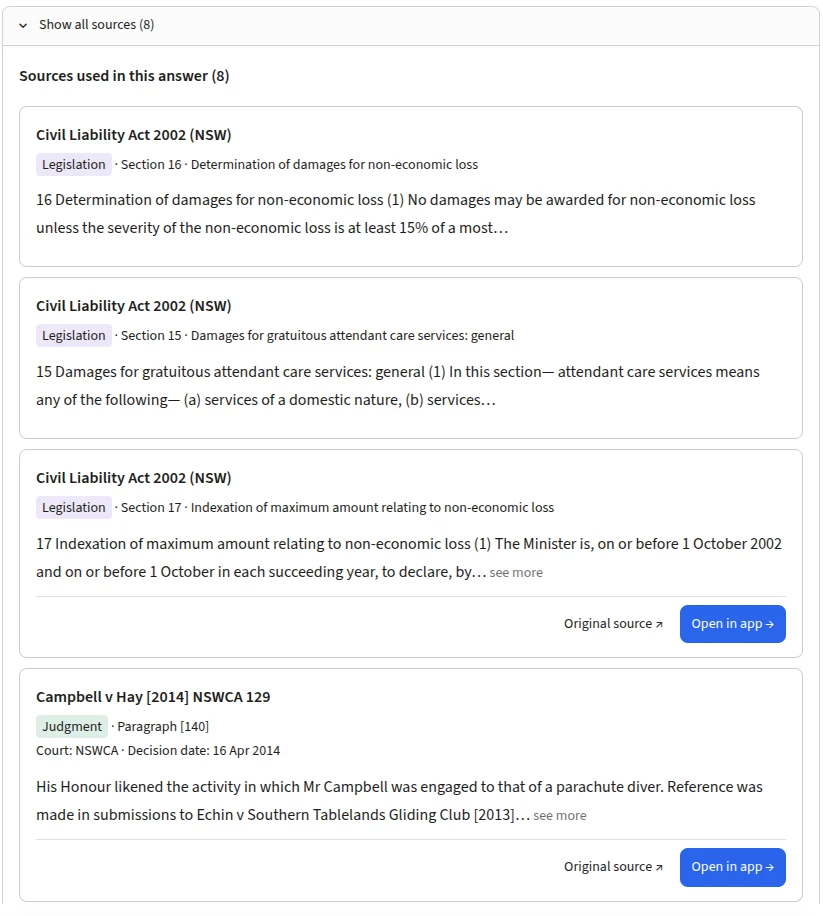
The project concerns the Civil Liability Act 2002 (NSW) and relevant NSW judgments. A defined corpus makes the research scope explicit rather than suggesting universal legal coverage.
Retrieve supporting material
BGE embeddings and ChromaDB support vector retrieval. The architecture pairs retrieved material with natural-language research and case-summary workflows.
Make sources part of the workflow
The design centres on traceability to source documents. A generated summary is a route into the material, and the underlying text remains necessary for checking its meaning.
Constraints & trade-offs
04Retrieval can miss relevant passages, and generated summaries can still be wrong. Source traceability does not establish automated citation validation or guarantee correctness. The platform assists research and does not provide legal advice or predictions.
Outcome & reflection
05A team capstone research-assistance platform combining vector search, local model tooling, structured data and a user-facing research interface. No public deployment or repository is listed.
This work connects my interests in databases and natural language processing: the value of a model-backed system depends on the information it can retrieve and how clearly a user can inspect that information.
Screens & outputs
2 IMAGESSelect an image to open it at full size.